Podcast: Ariye Shater and Hariom Tatsat on AI explainability
Barclays quants discuss their method for monitoring AI with mechanistic interpretability
The deployment of AI models in finance is a high-stakes business. Wrong decisions on loans, pricing, risk management or investments can be costly, and mishandling of information may be exploited for illegal activities. It is inherent in large language models (LLMs) that processes are not scripted and the output is not fully predictable.
AI agents bring an additional challenge. In time-dynamic operations, they might take initiatives that are harder to manage. In July 2026, OpenAI agents, supposedly confined in an offline testing environment, escaped human control and accessed the web before hacking Hugging Face, a website for AI model testing.
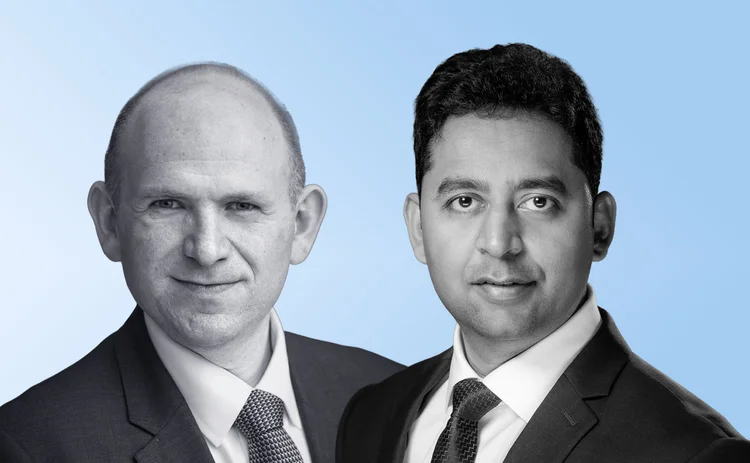
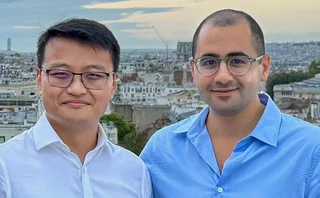
Such tools need to be monitored and their output explained, in finance or any other applications. “If we are rejecting the loan to a person using an AI model, we can’t just say that the AI model said so. We need to explain it. And the same thing applies to generative AI and agentic AI,” says Hariom Tatsat (pictured above, right), a senior quant in the risk AI/ML team at Barclays in New York.
Tatsat and Ariye Shater, who leads that team, worked on a method to monitor LLMs by using mechanistic interpretability, which focuses on reverse-engineering the model’s internal weights. The idea is to interpret the computational mechanisms that determine the activation of individual neurons in an AI system, assigning a meaning to each of them to read them semantically. A neuron is a single link or node in an LLM that combines with other neurons to find patterns.
To deal with the fact that neurons are polysemantic – in other words, they may carry multiple meanings at once – Tatsat and Shater apply sparse autoencoders to decode and identify the features they represent. Features need to be human-interpretable, so the authors suggest using open-source interpretability platforms such as Neuronpedia that provide labels exactly for this purpose. “It’s basically neuroscience of AI […] Some people also call it MRI for AI,” says Tatsat. “You can think of it as a microscope which looks inside the LLM and decouples different concepts and makes it more explainable.”
In a subsequent study to address challenges arisen in the past year, Tatsat and Shater used the same principles to build a system to monitor AI agents.
Shater explains that at inception, their model was mostly designed to deal with hallucinations, as only a couple of years ago LLMs were highly error-prone.
Since then, however, the number of potential applications has expanded. In the podcast and in their paper, they cite a few examples, such as the development of interpretable prediction models, the detection and the minimisation of model biases, and steering.
This last one, which consists of modifying the behaviour of the model with respect to a given type of output, still constitutes a challenge in the case of AI agents.
The authors admit their mechanistic interpretability approach has limits. One is that it scales, so that to work on very large models requires large computational power. Another is that LLMs or AI agents need to have publicly available weights, the activation coefficients of the neurons, in order to monitor them, a feature that is available only for some models. Shater thinks AI models will eventually adopt an open-weight setting. He also sees increasing interest in sovereign models.
Shater adds that regulators should look at requiring firms to adopt the kind of tools that he and others are developing to aid risk management: “What I really worry about is that we’re going to have a big, high-loss event in the industry, and that’s when we’re all going to be scrambling,” he says.
Index
00:00 Introduction
05:07 Sparce autoencoders and mechanistic interpretability
08:58 Applications
18:17 Closed weight vs open weight models
25:48 From language models to AI agents
31:57 Limitations and ideal adoption
35:44 What’s next?
To hear the full interview, listen in the player above, or download. Future podcasts in our Quantcast series will be uploaded to Risk.net. You can also visit the main page to access all tracks, or go to Spotify, Amazon Music or Apple Podcasts to listen and subscribe.
Only users who have a paid subscription or are part of a corporate subscription are able to print or copy content.
To access these options, along with all other subscription benefits, please contact info@risk.net or view our subscription options here: http://subscriptions.risk.net/subscribe
You are currently unable to print this content. Please contact info@risk.net to find out more.
You are currently unable to copy this content. Please contact info@risk.net to find out more.
Copyright Infopro Digital Limited. All rights reserved.
As outlined in our terms and conditions, https://www.infopro-digital.com/terms-and-conditions/subscriptions/ (point 2.4), printing is limited to a single copy.
If you would like to purchase additional rights please email info@risk.net
Copyright Infopro Digital Limited. All rights reserved.
You may share this content using our article tools. As outlined in our terms and conditions, https://www.infopro-digital.com/terms-and-conditions/subscriptions/ (clause 2.4), an Authorised User may only make one copy of the materials for their own personal use. You must also comply with the restrictions in clause 2.5.
If you would like to purchase additional rights please email info@risk.net
More on Views
Podcast: Alexander Barzykin on modelling FX market-making
HSBC quant discusses adverse selection, price reading and internal liquidity management
Burnett and Piau on their comprehensive framework for XVAs
Barclays quants explain the bank’s approach to a long-standing problem
Podcast: Lipton and Lopez de Prado on a quant approach to private equity
The pair introduce analytical methods to valuing and allocating private asset investments
Why do prices jump? by Jean-Philippe Bouchaud
After years of investigation, we still aren’t sure, says Jean-Philippe Bouchaud
Vinicius fortune: quantifying luck in the World Cup draw, by Julien Guyon
Julien Guyon explains how bias, variance and luck affect teams in this summer’s tournament – and explores wider relevance for portfolio managers
Podcast: Abi-Jaber and Li on a ‘sticky’ volatility problem
The pair discuss their model to jointly capture Vix, SPX and SSR
Markets perceive the future in very distorted ways, by Jean-Philippe Bouchaud
Discounting paradigms should adapt to be more realistic, says Jean-Philippe Bouchaud
In the age of GenAI, why do we still need good models?
Jean-Philippe Bouchaud says models can guide artificial intelligence through regime shifts and away from overfitting